@zhangyy
2018-11-28T02:38:15.000000Z
字数 8366
阅读 602
hbase 数据库深入使用与相关数据的加载
hbase的部分
- 一:hbase 数据检索流程
- 二:hbase 数据库java api 调用
- 三:hbase 各个服务的作用
- 四:hbase 与mapreduce集成
一:hbase 数据检索流程
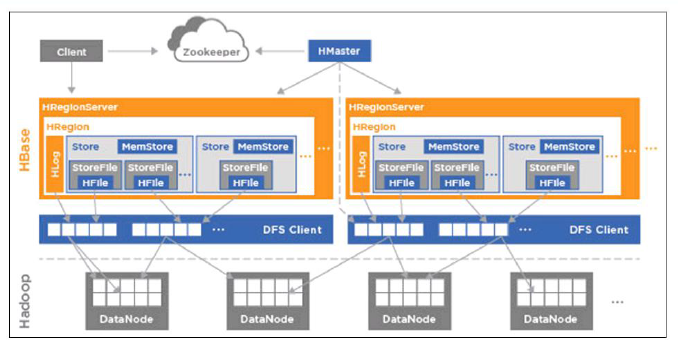
1.1 hbase 数据检索流程图:
1.2 hbase 读的流程:
读流程:1、client请求zookeeper集群(root/meta)(meta)--有多少table,table有哪些region(startrow、stoprow)2、client找到region对应的region server3、region server响应客户端请求
1.3. hhbase 写的流程
1、client请求zookeeper集群,该数据应该写入哪个region2、向region所在的region server 发起写请求3、数据先写进HLOG(WAL)4、然后写入memstore(flush)5、当memstore达到阀值,写入storefile(compact)6、当storefile达到阀值,合并成新的storefile7、当region达到阀值,当前region会划分为两个新的region(split)
1.4 hbase 读写流程存储核心的三个机制
1. flush机制:当memstore满了以后会flush陈一个storefile2. compact机制:当storefile达到阀值,合并storefile,合并过程中cell版本合并和数据删除3. split机制:当region不断增大,达到阀值,region会分成两个新的region
二:hbase 数据库java api 调用
2.1 eclipse 环境配置
更改maven 的源:上传repository.tar.gz
cd .m2mv repository repository.bak2016612rz repository.tar.gztar -zxvf repository.tar.gzcd /home/hadoop/yangyang/hbasecp -p hbase-site.xml log4j.properties /home/hadoop/workspace/studyhbase/src/main/rescourse
更改eclipse 的pom.xml
增加:
<dependency><groupId>org.apache.hbase</groupId><artifactId>hbase-server</artifactId><version>0.98.6-hadoop2</version></dependency><dependency><groupId>org.apache.hbase</groupId><artifactId>hbase-client</artifactId><version>0.98.6-hadoop2</version></dependency>
2.2 hbase java api 掉用:
package org.apache.hadoop.hbase;import java.io.IOException;import org.apache.hadoop.conf.Configuration;import org.apache.hadoop.hbase.Cell;import org.apache.hadoop.hbase.CellUtil;import org.apache.hadoop.hbase.HBaseConfiguration;import org.apache.hadoop.hbase.client.Get;import org.apache.hadoop.hbase.client.HBaseAdmin;import org.apache.hadoop.hbase.client.HTable;import org.apache.hadoop.hbase.client.Put;import org.apache.hadoop.hbase.client.Result;import org.apache.hadoop.hbase.client.ResultScanner;import org.apache.hadoop.hbase.client.Scan;import org.apache.hadoop.hbase.util.Bytes;public class HbaseOperation {/**** @param args* @throws IOException*/public static HTable getTable(String tableName) throws IOException {// Get configurationConfiguration conf = HBaseConfiguration.create();// Get TableHTable table = new HTable(conf, tableName);return table;}public static void getData() throws IOException {HTable table = HbaseOperation.getTable("user");// Get DataGet get = new Get(Bytes.toBytes("1001"));Result result = table.get(get);Cell[] cells = result.rawCells();for (Cell cell : cells) {System.out.print(Bytes.toString(CellUtil.cloneFamily(cell)) + ":");System.out.print(Bytes.toString(CellUtil.cloneQualifier(cell))+ "==>");System.out.println(Bytes.toString(CellUtil.cloneValue(cell)));}table.close();}/**** @param args* @throws IOException*/public static void putData() throws IOException {HTable table = HbaseOperation.getTable("user");Put put = new Put(Bytes.toBytes("1004"));put.add(Bytes.toBytes("info"), Bytes.toBytes("name"),Bytes.toBytes("zhaoliu"));put.add(Bytes.toBytes("info"), Bytes.toBytes("age"),Bytes.toBytes("50"));put.add(Bytes.toBytes("info"), Bytes.toBytes("sex"),Bytes.toBytes("male"));table.put(put);table.close();}public static void main(String[] args) throws IOException {HTable table = HbaseOperation.getTable("user");Scan scan = new Scan();scan.setStartRow(Bytes.toBytes("1001")) ;scan.setStopRow(Bytes.toBytes("1002")) ;ResultScanner resultScanner = table.getScanner(scan);for (Result res : resultScanner) {Cell[] ress = res.rawCells();for (Cell cell : ress) {System.out.print(Bytes.toString(CellUtil.cloneRow(cell))+ "\t");System.out.print(Bytes.toString(CellUtil.cloneFamily(cell))+ ":");System.out.print(Bytes.toString(CellUtil.cloneQualifier(cell))+ "==>");System.out.println(Bytes.toString(CellUtil.cloneValue(cell)));}table.close();}}}
三:hbase 各个服务的作用
3.1 Hmaster 作用:
1、为region server分配region2、负责region server的负责均衡3、发现失效的region server,需要重新分配其上的region4、监听zk,基于zookeeper感应region server的上下线5、监听zk,基于zookeeper来保证HA6、不参与客户端数据读写访问7、负载低(通常情况下可以把它和其他服务器(NN/SNN)整合在一起)8、无单点故障(SPOF)
3.2 Hregionserver 作用:
1、维护master分配给它的region2、响应客户端的IO访问请求(读写)3、处理region的flush、compact、split4、维护region的cache
3.4 zookeeper 作用:
1、保证集群里面只有一个master(HA)2、保存了root region的位置(meta),访问入口地址3、实时监控region server的状态,及时通知region server上下线消息给master4、存储了hbase的schema,包括哪些table,每个表有哪些列簇
四:hbase 与mapreduce集成
4.1 hbase 获取jar命令
bin/hbase mapredcp
4.2 配置环境变量
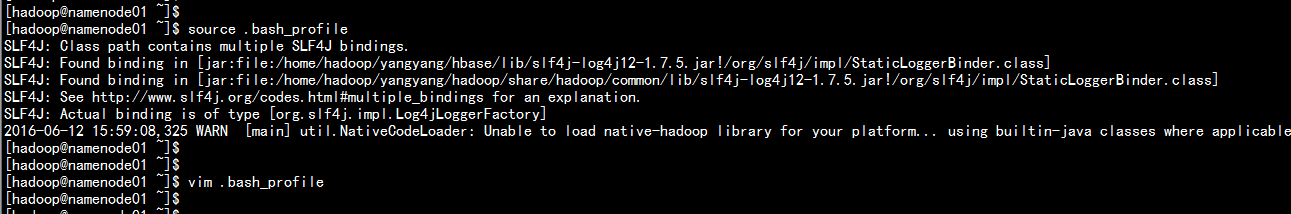
vim .bash_profileexport HADOOP_HOME=/home/hadoop/yangyang/hadoopexport HBASE_HOME=/home/hadoop/yangyang/hbaseexport HADOOP_CLASSPATH=`$HBASE_HOME/bin/hbase mapredcp`PATH=$PATH:$HOME/bin:$JAVA_HOME/bin:${HADOOP_HOME}/bin:${MAVEN_HOME}/bin:${HBASE_HOME}:${HADOOP_CLASSPATH}soure .bash_profile
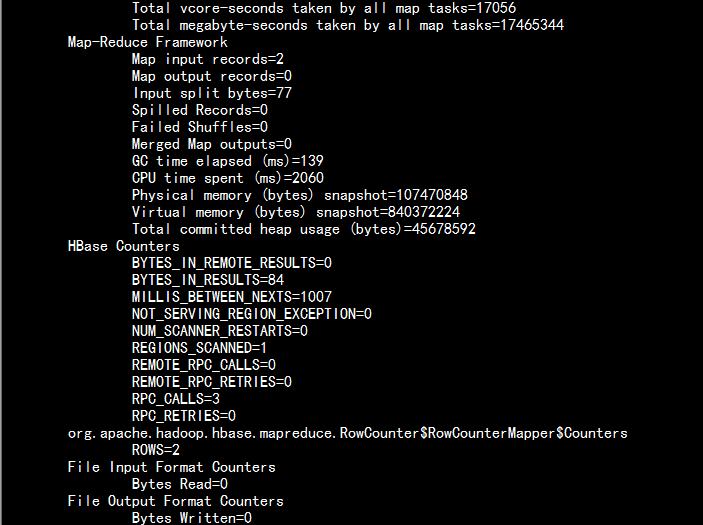
4.3 统计一个hbase表:
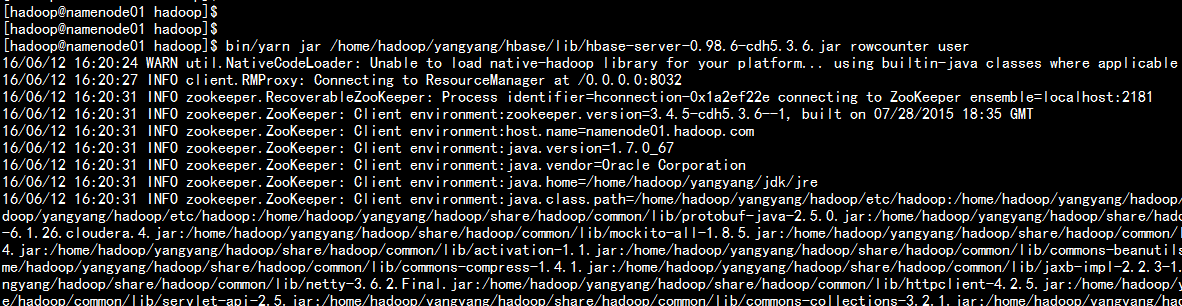
cd /home/hadoop/yangyang/hadoopbin/yarn jar /home/hadoop/yangyang/hbase/lib/hbase-server-0.98.6-cdh5.3.6.jar rowcounter user
4.4 导入一个生成的hbase 表的in.tsv
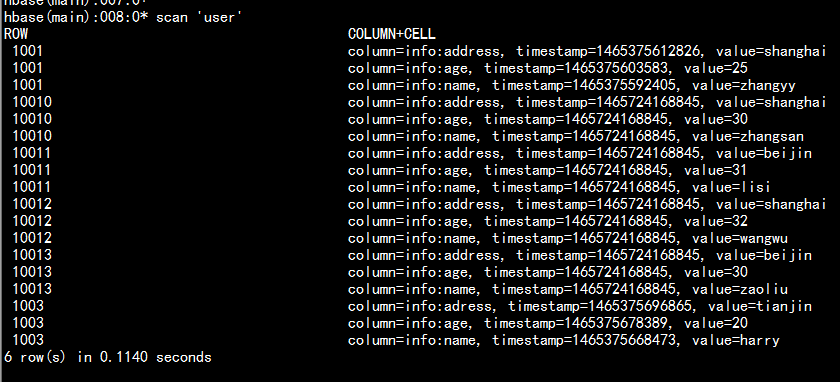
vim in.tsv---10010 zhangsan 30 shanghai10011 lisi 31 beijin10012 wangwu 32 shanghai10013 zaoliu 30 beijin
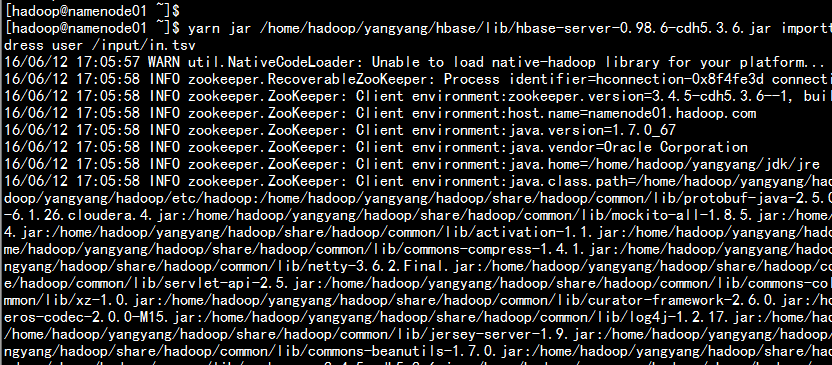
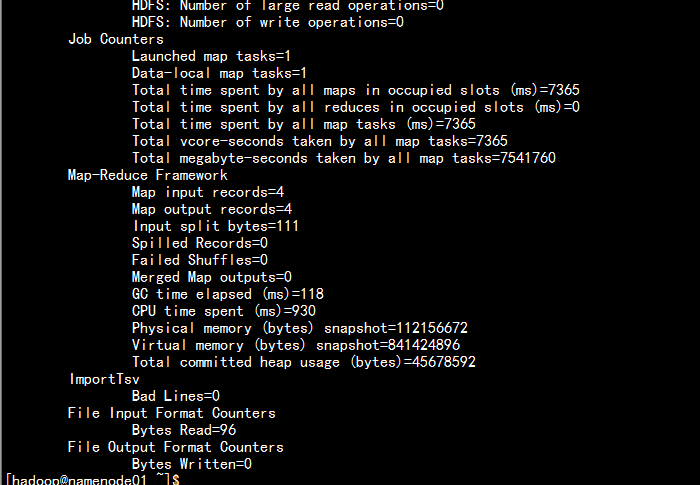
hdfs dfs -put in.tsv /inputyarn jar /home/hadoop/yangyang/hbase/lib/hbase-server-0.98.6-cdh5.3.6.jar importtsv -Dimporttsv.columns=HBASE_ROW_KEY,info:name,info:age,info:address user /input/in.tsv
4.5 使用BulkLoad加载数据
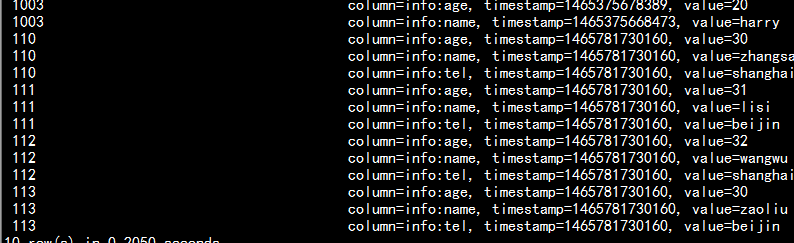
vim out.tsv110 zhangsan 30 shanghai111 lisi 31 beijin112 wangwu 32 shanghai113 zaoliu 30 beijin
hdfs dfs -put out.tsv /input<!-- 将tsv 文件转换成hfile 文件(在hdfs 上面)-->yarn jar /home/hadoop/yangyang/hbase/lib/hbase-server-0.98.6-cdh5.3.6.jar importtsv -Dimporttsv.bulk.output=/hfileoutput/ -Dimporttsv.columns=HBASE_ROW_KEY,info:name,info:age,info:tel user /input/out.tsv<!-- 将hfile 加载到hbase 的表中yarn jar /home/hadoop/yangyang/hbase/lib/hbase-server-0.98.6-cdh5.3.6.jar completebulkload /hfileoutput user
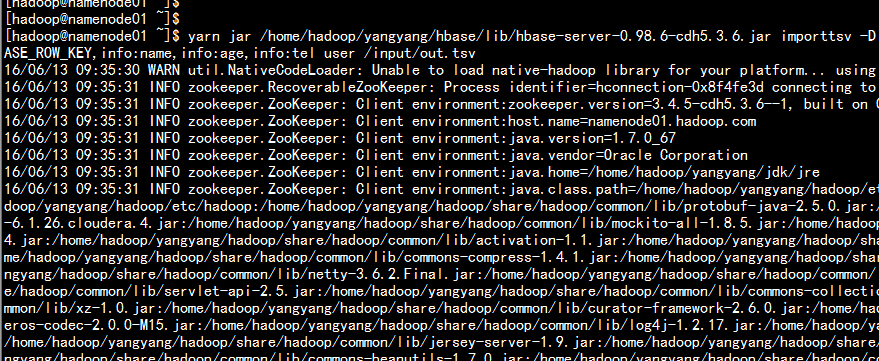
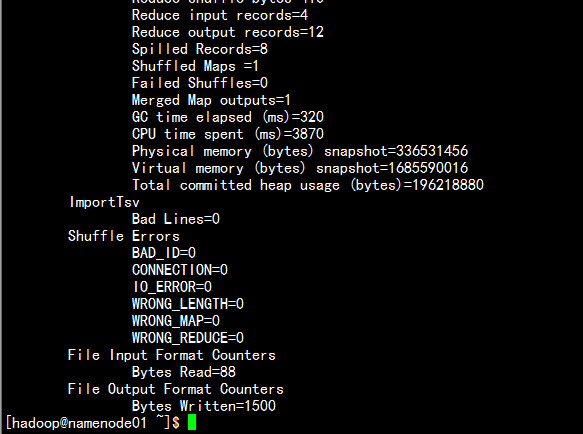
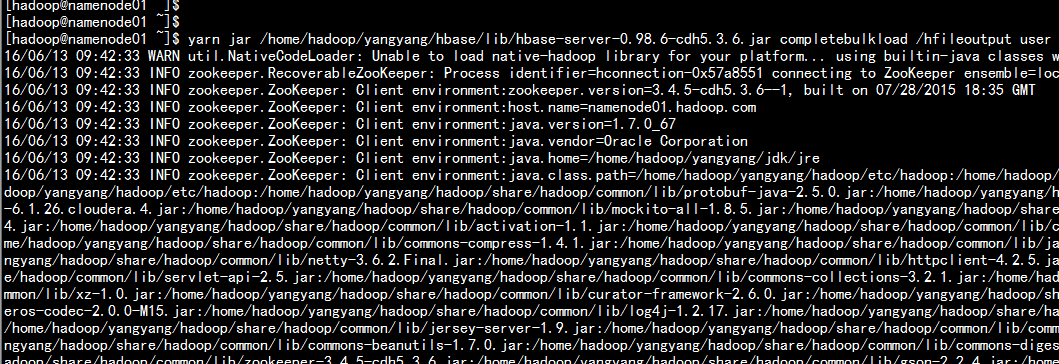
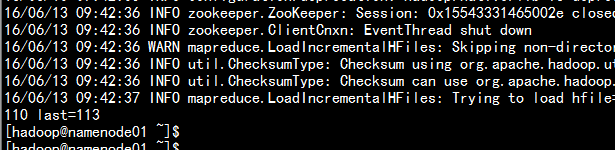
4.6 hbase 表中提取相关字段,生成新的表
提取hbase 表中的user 表的name 与age 字段 生成新表student
package org.apache.hadoop.studyhbase;import java.io.IOException;import org.apache.hadoop.conf.Configuration;import org.apache.hadoop.conf.Configured;import org.apache.hadoop.hbase.Cell;import org.apache.hadoop.hbase.CellUtil;import org.apache.hadoop.hbase.HBaseConfiguration;import org.apache.hadoop.hbase.client.Put;import org.apache.hadoop.hbase.client.Result;import org.apache.hadoop.hbase.client.Scan;import org.apache.hadoop.hbase.io.ImmutableBytesWritable;import org.apache.hadoop.hbase.mapreduce.TableMapReduceUtil;import org.apache.hadoop.hbase.mapreduce.TableMapper;import org.apache.hadoop.hbase.mapreduce.TableReducer;import org.apache.hadoop.hbase.util.Bytes;import org.apache.hadoop.io.NullWritable;import org.apache.hadoop.mapreduce.Job;import org.apache.hadoop.util.Tool;import org.apache.hadoop.util.ToolRunner;public class User2StudentMapReduce extends Configured implements Tool{// step 1: Mapperpublic static class ReadUserMapper //extends TableMapper<ImmutableBytesWritable, Put>{@Overrideprotected void map(ImmutableBytesWritable key, Result value,Context context)throws IOException, InterruptedException {// user: name & age -> student: name & age : put// create PutPut put = new Put(key.get()) ;// add columnfor(Cell cell: value.rawCells()){// add family: infoif("info".equals(Bytes.toString(CellUtil.cloneFamily(cell)))){// add column: nameif("name".equals(Bytes.toString(CellUtil.cloneQualifier(cell)))){put.add(cell) ;// CellUtil.cloneValue(cell)// put.add(family, qualifier, value) ;}// add column: ageelse if("age".equals(Bytes.toString(CellUtil.cloneQualifier(cell)))){put.add(cell) ;}}}// context outputcontext.write(key, put);}}// step 2: Reducerpublic static class WriteStudentReducer //extends TableReducer<ImmutableBytesWritable, Put, NullWritable>{@Overrideprotected void reduce(ImmutableBytesWritable key, Iterable<Put> values,Context context) throws IOException, InterruptedException {for(Put put : values){context.write(NullWritable.get(), put);}}}// step 3: Driverpublic int run(String[] args) throws Exception {// 1) ConfigurationConfiguration conf = this.getConf();// 2) create jobJob job = Job.getInstance(conf, this.getClass().getSimpleName()) ;job.setJarByClass(User2StudentMapReduce.class);// 3) set job// input -> mapper -> shuffle -> reducer -> outputScan scan = new Scan() ;scan.setCacheBlocks(false);scan.setCaching(500); // 1 is the default in Scan, which will be bad for MapReduce jobsTableMapReduceUtil.initTableMapperJob("user", // input tablescan, // Scan instance to control CF and attribute selectionReadUserMapper.class, // mapper classImmutableBytesWritable.class, // mapper output keyPut.class, // mapper output valuejob //);TableMapReduceUtil.initTableReducerJob("student", // output tableWriteStudentReducer.class, // reducer classjob //);job.setNumReduceTasks(1); // at least one, adjust as requiredboolean isSuccess = job.waitForCompletion(true);if (!isSuccess) {throw new IOException("error with job!");}return isSuccess ? 0 : 1;}public static void main(String[] args) throws Exception {Configuration conf = HBaseConfiguration.create();int status = ToolRunner.run(//conf, //new User2StudentMapReduce(), //args //);System.exit(status);}}
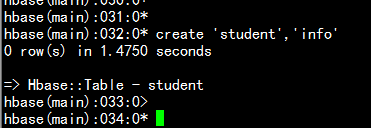
去hbase 上面新建空表studentcreate 'student','info'
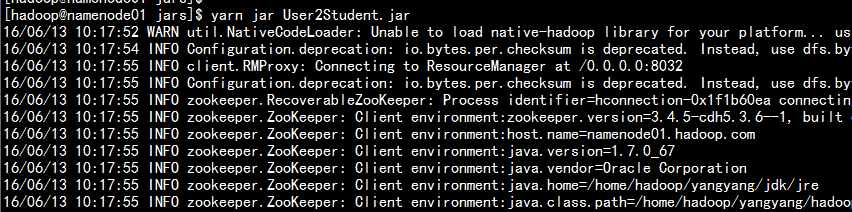
导出新生成jar包User2Student.jar运行:
cd /home/hadoop/jarsyarn jar User2Student.jar
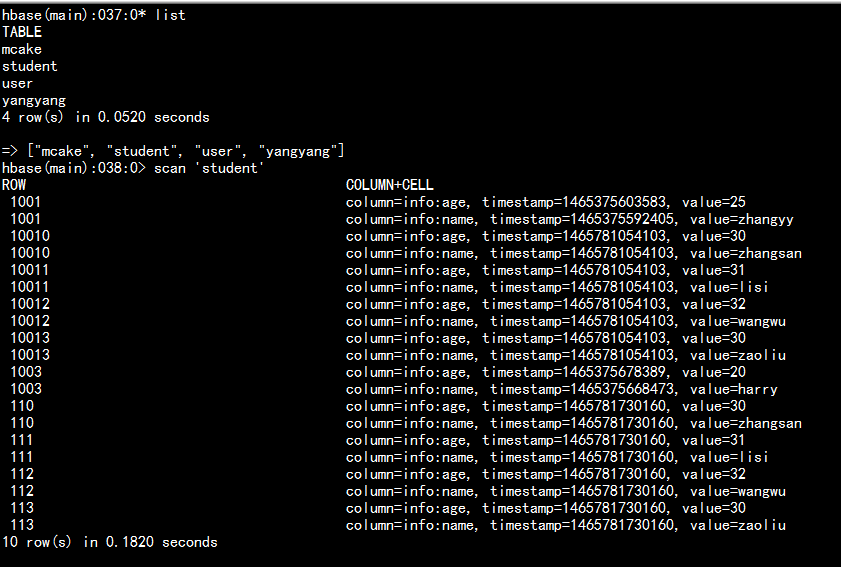
查询hbase进行验证: